
Every Dynamics 365 app and every Power App you build stores its records in the same place: Microsoft Dataverse. That makes Dataverse data quality the foundation everything else stands on — sales dashboards, marketing journeys, custom apps and Copilot alike. This guide explains what Dataverse is, why its data decays, and how to keep it clean.
What is Microsoft Dataverse?
Microsoft Dataverse is the cloud data platform underneath Dynamics 365 and the Power Platform. It stores data in a set of tables (formerly “entities”) — standard ones like Account, Contact and Lead, plus any custom tables you create — and adds the layers a business database needs out of the box: role-based security, business rules, workflows, auditing and APIs. When you use Dynamics 365 Sales or Customer Service, you are using Dataverse. When you build a Power App or a Power Automate flow against your CRM data, you are reading and writing Dataverse tables.
The practical consequence: Dataverse data is shared. One Account table serves your sales app, your service console, your marketing tool, your custom Power Apps and Copilot. Clean it once and every app benefits; let it decay and every app suffers together.
Why data quality matters more in Dataverse than in a normal database
- One table, many writers. Users, imports, integrations, web forms and flows all create records in the same tables — each with its own idea of formatting and matching. This is how duplicates and inconsistencies are born.
- Everything downstream inherits the problems. A duplicate Account doesn’t just clutter a list; it splits the customer’s cases, opportunities and activity history across records in every app that reads the table.
- Copilot and AI read Dataverse directly. Microsoft’s AI features summarize whatever the tables contain. Fragmented or stale records produce confident, wrong answers.
- Service protection limits punish inefficiency. Dataverse throttles API-heavy operations, so cleanup approaches that hammer the API row-by-row are slow by design. Data quality tooling has to work in efficient, server-side batches.
The four failure modes of Dataverse data
1. Duplicates. The same customer as two Accounts, or as a Lead and a Contact. Native duplicate detection catches exact matches only — “Jon”/“John” and “Müller”/“Mueller” sail through. Our duplicate detection guide covers this failure mode in depth.
2. Incomplete records. Dataverse lets you make fields required at the form level, but imports, integrations and the API can bypass forms entirely. Completeness has to be measured and enforced at the data layer, not just the UI.
3. Inconsistent values. Free-text fields drift: three spellings of the same country, phone numbers in five formats, casing chaos. Every report that groups or filters by these fields quietly loses rows.
4. Stale records. People change jobs, companies rebrand. Without a review cadence, a Dataverse table becomes an archive that pretends to be current.
Data quality rules for Dataverse and Power Apps
The fix for incompleteness and inconsistency is data quality rules: conditions a record must meet, evaluated when it is created or changed, with the result shown to the user and rolled up for management. Dataverse has no built-in way to define such rules visually and report on them — which is exactly the gap the Data Quality App fills. Rules run on any table, standard or custom, apply to records arriving from any source, and every rule feeds a per-table score you can put on a dashboard or in Power BI.

Duplicate detection across Dataverse tables
Because all your apps share the same tables, deduplication in Dataverse pays off everywhere at once. A dependable setup combines fuzzy and phonetic matching (to catch what exact rules miss), scheduled background scans across millions of rows, bulk merge with master-record rules that preserve every related record, and point-of-entry checking so cleaned tables stay clean.

Monitoring: the habit that keeps Dataverse healthy
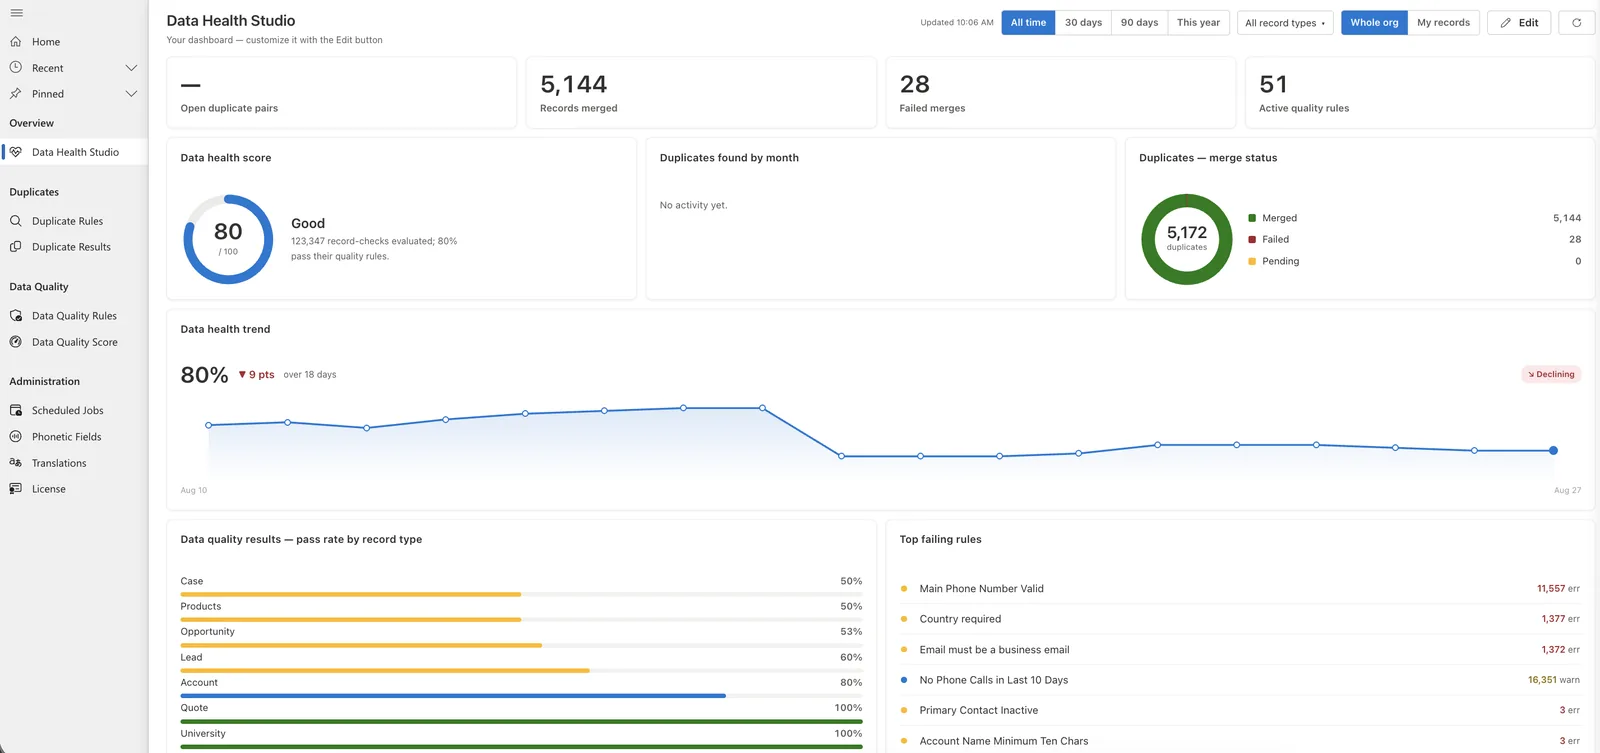
Data quality is a rate, not a state. The tables you cleaned this quarter are decaying next quarter. A monitoring dashboard that tracks duplicate rate, rule violations and completeness per table — visible to the people who own the data — is what turns a one-off cleanup into a durable asset.
Dataverse vs. Dynamics 365 vs. Power Apps: what’s the difference?
The three names confuse almost everyone, so here is the clean separation. Dataverse is the data platform: the tables, the security model, the APIs. Dynamics 365 is a family of ready-made business applications — Sales, Customer Service, Marketing and more — that Microsoft builds on top of Dataverse. Power Apps is the toolkit for building your own applications on that same platform. A “model-driven app” in Power Apps and Dynamics 365 Sales are, under the hood, the same kind of thing: user interfaces over Dataverse tables.
This is why data quality work done “for Dynamics 365” automatically covers your Power Apps, and vice versa. There is no separate cleanup per app — there is one set of tables, and one cleanup.
What native Dataverse duplicate detection can and cannot do
Dataverse ships with duplicate detection rules, and it is worth being precise about their limits before deciding whether they are enough for you:
- They can compare fields for exact matches (with options like case-insensitivity), warn users interactively on create and update, and run scheduled system jobs.
- They cannot do fuzzy matching (typos), phonetic matching (same-sound names), or compare across tables (a Lead against existing Contacts). Rule publishing is slow on large tables, there is a five-rule limit per table, and there is no bulk merge — the native merge dialog handles two records at a time, manually.
For a small, well-disciplined environment, native rules plus occasional manual merging can suffice. Past roughly 50,000 records per table — or the first time you meet a typo duplicate — you need matching and merging that the platform does not provide natively.
Five habits of clean Dataverse environments
- Every table has an owner who decides its required fields, its duplicate definition and its merge rules.
- Rules run at the point of entry — on user creates, imports and integration writes alike — so problems are caught when they are one record old, not one year old.
- Bulk detection runs on a schedulein the background, with results reviewed in small weekly batches rather than heroic quarterly sessions.
- The numbers are visible. Duplicate rate and completeness sit on a dashboard someone actually opens — ideally next to pipeline numbers in the monthly review.
- Integrations are held to the same standard as users. Every connector that writes to Dataverse either matches against existing records or is treated as a defect.
Frequently asked questions
Is Dataverse the same as the “Common Data Service”?
Yes — Common Data Service (CDS) was renamed Microsoft Dataverse in 2020. Older documentation and blog posts use the two names interchangeably.
Do data quality rules slow Dataverse down?
Well-built rules evaluate in milliseconds at save time and run heavy work (bulk detection, merging) as background jobs in efficient server-side batches, so users never wait on them. The performance risk comes from naive row-by-row API processing — which Dataverse throttles by design — not from rules as such.
Can I run duplicate detection on custom tables?
Yes. Because custom tables are first-class Dataverse tables, the Data Quality App’s detection, merging and rules work on them exactly as on Accounts or Contacts — which matters, because custom tables are where governance is usually thinnest.
How do I check my Dataverse data quality right now?
Two free options: install the free 15-day trial in your environment for a full-database duplicate report, or export a table and drop it into the free duplicate checker for an instant browser-based check.
Where to start
Measure first. Run a free 15-day trial on your environment — 15 days, full database, no card —. Once you can see the numbers, the cleanup plans in our Dynamics 365 data quality guide apply to Dataverse exactly as written — because Dynamics 365 data is Dataverse data.
Improve your data quality in Dynamics 365
The Data Quality App keeps records complete and correct with data quality rules at the point of entry, finds duplicates with fuzzy and phonetic matching, resolves them with bulk merge and measures your data health over 30, 60 and 90 days. Native in your own environment, free for 15 days.